A PDF can display perfectly readable text on the screen while technically being a flat image, without any exploitable text layer. The distinction between an image PDF and a PDF with functional OCR recognition affects full-text search, indexing, accessibility, and data extraction. Here, we detail concrete methods to quickly determine this.
Reading order after OCR: the test that most guides overlook
A PDF can contain an OCR text layer and still be unusable. The problem arises with multi-column documents, tables, and complex layouts: OCR recognizes characters but not the logical structure of the document.
To verify this, select a block of text in a tabular or multi-column area, copy it, and then paste it into a plain text editor. If the lines mix between columns or if the cells of a table concatenate without a separator, the OCR layer is present but poorly structured. The file will pass a basic Ctrl+F test while producing aberrant results during automated extraction.
This check is particularly critical for automated document workflows (invoice parsing, legal archiving, database feeding). A “recognized” PDF in the strict sense but with an incorrect reading order generates silent errors downstream.
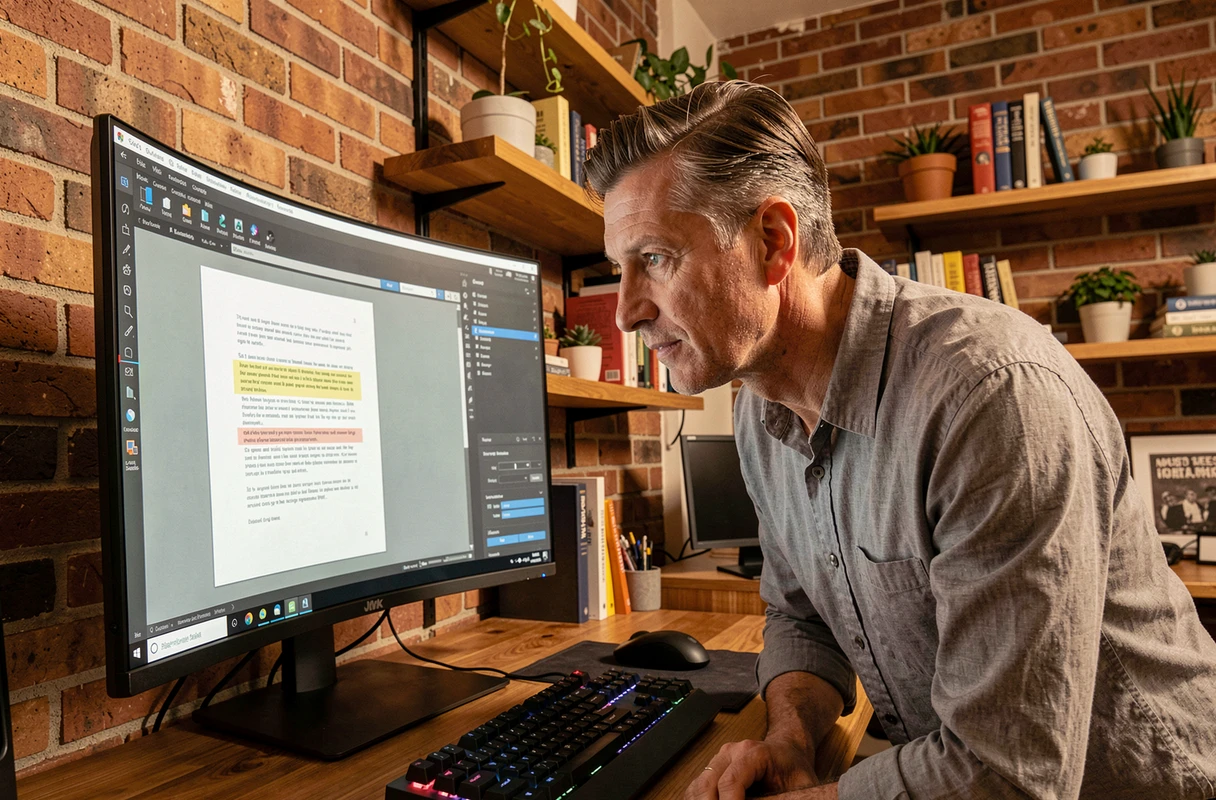
Cursor selection and Ctrl+F search in a PDF
The fastest method remains the direct selection test. Open the PDF in any reader (Adobe Reader, Foxit, browser), then try to highlight an isolated word with the cursor. Two possible results:
- The word highlights individually, character by character: a text layer exists. The PDF contains native text or has already been processed by OCR.
- The selection captures the entire page as a single block, or nothing is selected: the file is an image without a text layer. OCR has not been applied.
Complete this initial diagnosis with a Ctrl+F (or Cmd+F on macOS). Type a word visible on the screen. If the search returns no results while the word is clearly displayed, the PDF is a scanned image. We recommend knowing how to check the character recognition of a PDF before engaging in any extraction or archiving processing.
These two tests combined take less than ten seconds and require no specialized software.
Searchable PDF and editable PDF: a common confusion with technical consequences
The distinction between these two types of files is often blurred in consumer tools, even though it has a direct impact on document workflows.
Searchable PDF
The original image is preserved in a visible layer. An invisible text layer, generated by OCR, is overlaid underneath. The visual rendering remains identical to the original scan. Full-text search and copy-paste work, but the text is not directly editable in a standard PDF editor.
Editable PDF after OCR
The OCR engine reconstructs the content into native text objects, replacing the image with substituted fonts and repositioned blocks. The layout may be degraded: misaligned line breaks, approximate fonts, deconstructed tables. This format is suitable for reuse in a word processor (Word, LibreOffice), but not for faithful archiving of the source document.
In practice, for archiving and document compliance, the searchable format (image + invisible text layer) is preferable. For content re-editing, the editable format is relevant despite its visual fidelity limitations.
Check OCR quality beyond simple detection
Confirming the presence of a text layer is not enough. Poor quality OCR produces selectable text but riddled with errors. Here are additional checkpoints:
- Copy a complete paragraph and paste it into an editor. Count the misrecognized characters: substituted letters (rn read as m, l read as 1), missing spaces, broken ligatures.
- Test the search on terms specific to the document (proper nouns, references, acronyms). These elements are the first to be misrecognized by OCR engines.
- On multilingual documents, check that accented characters are correctly rendered. An OCR set up in English on a French text will systematically fail on é, è, ê, ù.
The quality of OCR directly depends on the resolution of the source scan. A document scanned below 200 dpi produces degraded recognition, particularly on text bodies smaller than 10 points.
Quick diagnostic tools for large PDF files
On a batch of several dozen or hundreds of files, manual tests do not scale. Several approaches allow for automating the verification.
In Adobe Acrobat Pro, the “Recognize Text” function indicates whether an OCR layer already exists before starting the processing. It is a reliable binary indicator, but limited to one file at a time without additional scripting.
Python libraries like PyMuPDF or pdfplumber allow for programmatically extracting the text layer from a PDF. If the extraction returns an empty string on a page that visually contains text, the file is an un-OCRed image. This type of script can be deployed in a few lines and processes entire batches in minutes.
For organizations managing regular document flows, we recommend integrating this automated check upstream of any indexing or archiving chain, rather than correcting errors afterward.
OCR verification is not a one-time act but a recurring quality control. A document correctly recognized today may pose problems tomorrow if the output format or OCR engine changes between two batches. Integrating a systematic validation test into the document pipeline remains the only reliable guarantee over time.